Kolibri Computes Like a Small Model. It Still Needs a Data Center.
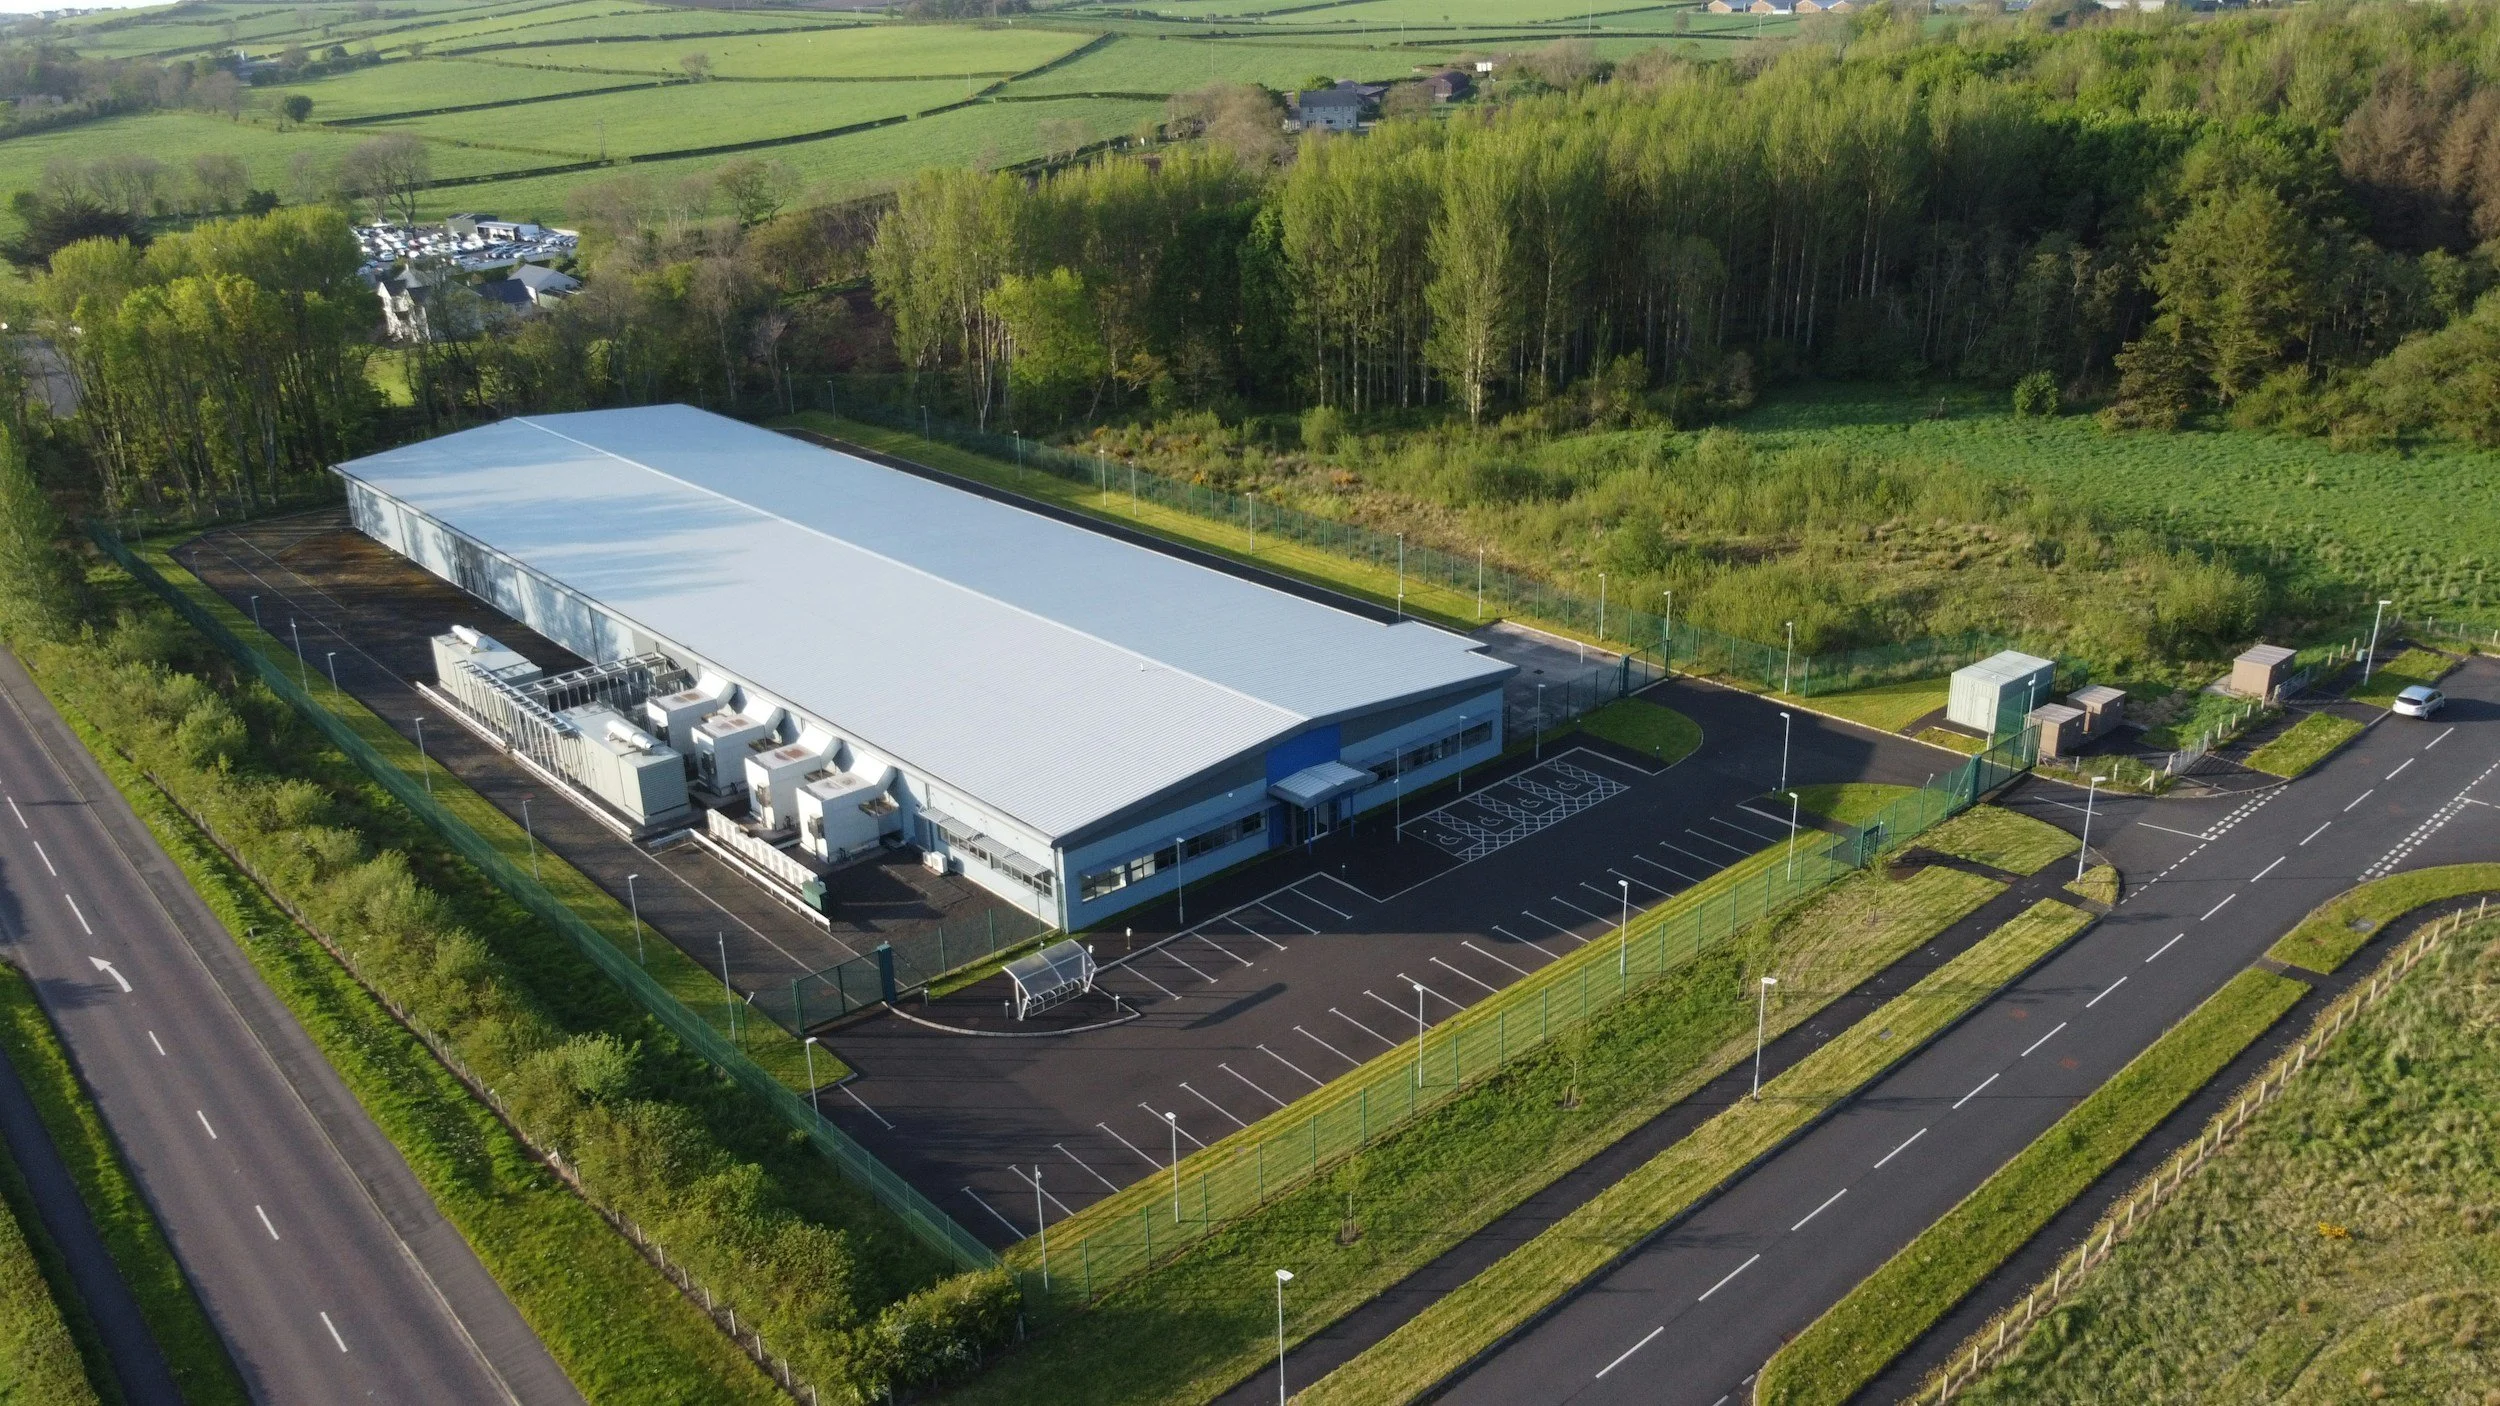
Data Center Exterior
By Ellis Ward, Resident Expert, AI Systems & Research Norms
On German Unity Day, 3 October 2026, Aleph Alpha released Kolibri-1 as open weights under the Apache 2.0 license on Hugging Face, accompanied by a 189-page technical report. The model is bilingual German-English, built on mixture-of-experts architecture, trained entirely on infrastructure in Germany and Finland, and positioned as a sovereign option for European regulated industries. Those claims each deserve a close reading, because they are not all the same kind of claim.
What the numbers actually say
Total parameters: 78.1 billion.
Active parameters per token: 3.46 billion.
Native context window: 262,144 tokens.
Validated context window: 1,048,576 tokens.
Weight size (FP8): about 78 GB.
Minimum GPU requirement: Two A100 80 GB, or one H200 / B200 / B300.
The gap between 78.1 billion and 3.46 billion is the whole story of mixture-of-experts, and it matters for anyone budgeting hardware.
How mixture-of-experts actually works
A standard dense model runs every parameter on every token. Kolibri-1 does not. Its 50 transformer layers each contain 384 routed experts plus one shared expert. A small learned router looks at each incoming token and picks 6 of those 384 routed experts to actually compute with. The rest sit idle for that token.
The result: Kolibri-1 computes like a roughly 3.5-billion-parameter model on each token, which is why inference is fast and cheap relative to its total size. That is the genuine win.
The catch is that all 78.1 billion parameters, all 384 experts per layer, must be loaded into GPU memory before the router can route anything. The model cannot decide to leave experts at home. This is why the minimum spec is two A100 80 GB cards, and why "computes like a small model" and "needs data-center hardware" are both true at the same time.
One other thing: the 384 experts do not divide neatly into 384 subjects. They are statistical patterns, not labeled departments. A legal-document expert and a Python-code expert would be a convenient fiction. What the router actually learns is messier and more distributed than the subject-folder metaphor suggests.
The tokenizer advantage is real and measurable
Kolibri-1 uses a 128,000-vocabulary tokenizer built with UniBPE, an algorithm designed to handle morphologically rich languages efficiently. German compounds long words rather than spacing them, which punishes tokenizers built primarily on English text.
The technical report cites one concrete comparison: the German word Bundesverfassungsgericht costs 2 tokens in Kolibri versus 6 tokens in the GPT-5 tokenizer (o200k_base). More systematically, the report claims 11.2 percent fewer German tokens on average, which translates directly into shorter context usage and lower inference cost for German text.
An independent test on the German Basic Law found Kolibri-1 used 35,190 tokens versus 41,482 for the GPT tokenizer, roughly a 15 percent difference on that document. Fewer tokens means more text fits in the same context window, faster generation, and lower API cost at any price-per-token rate.